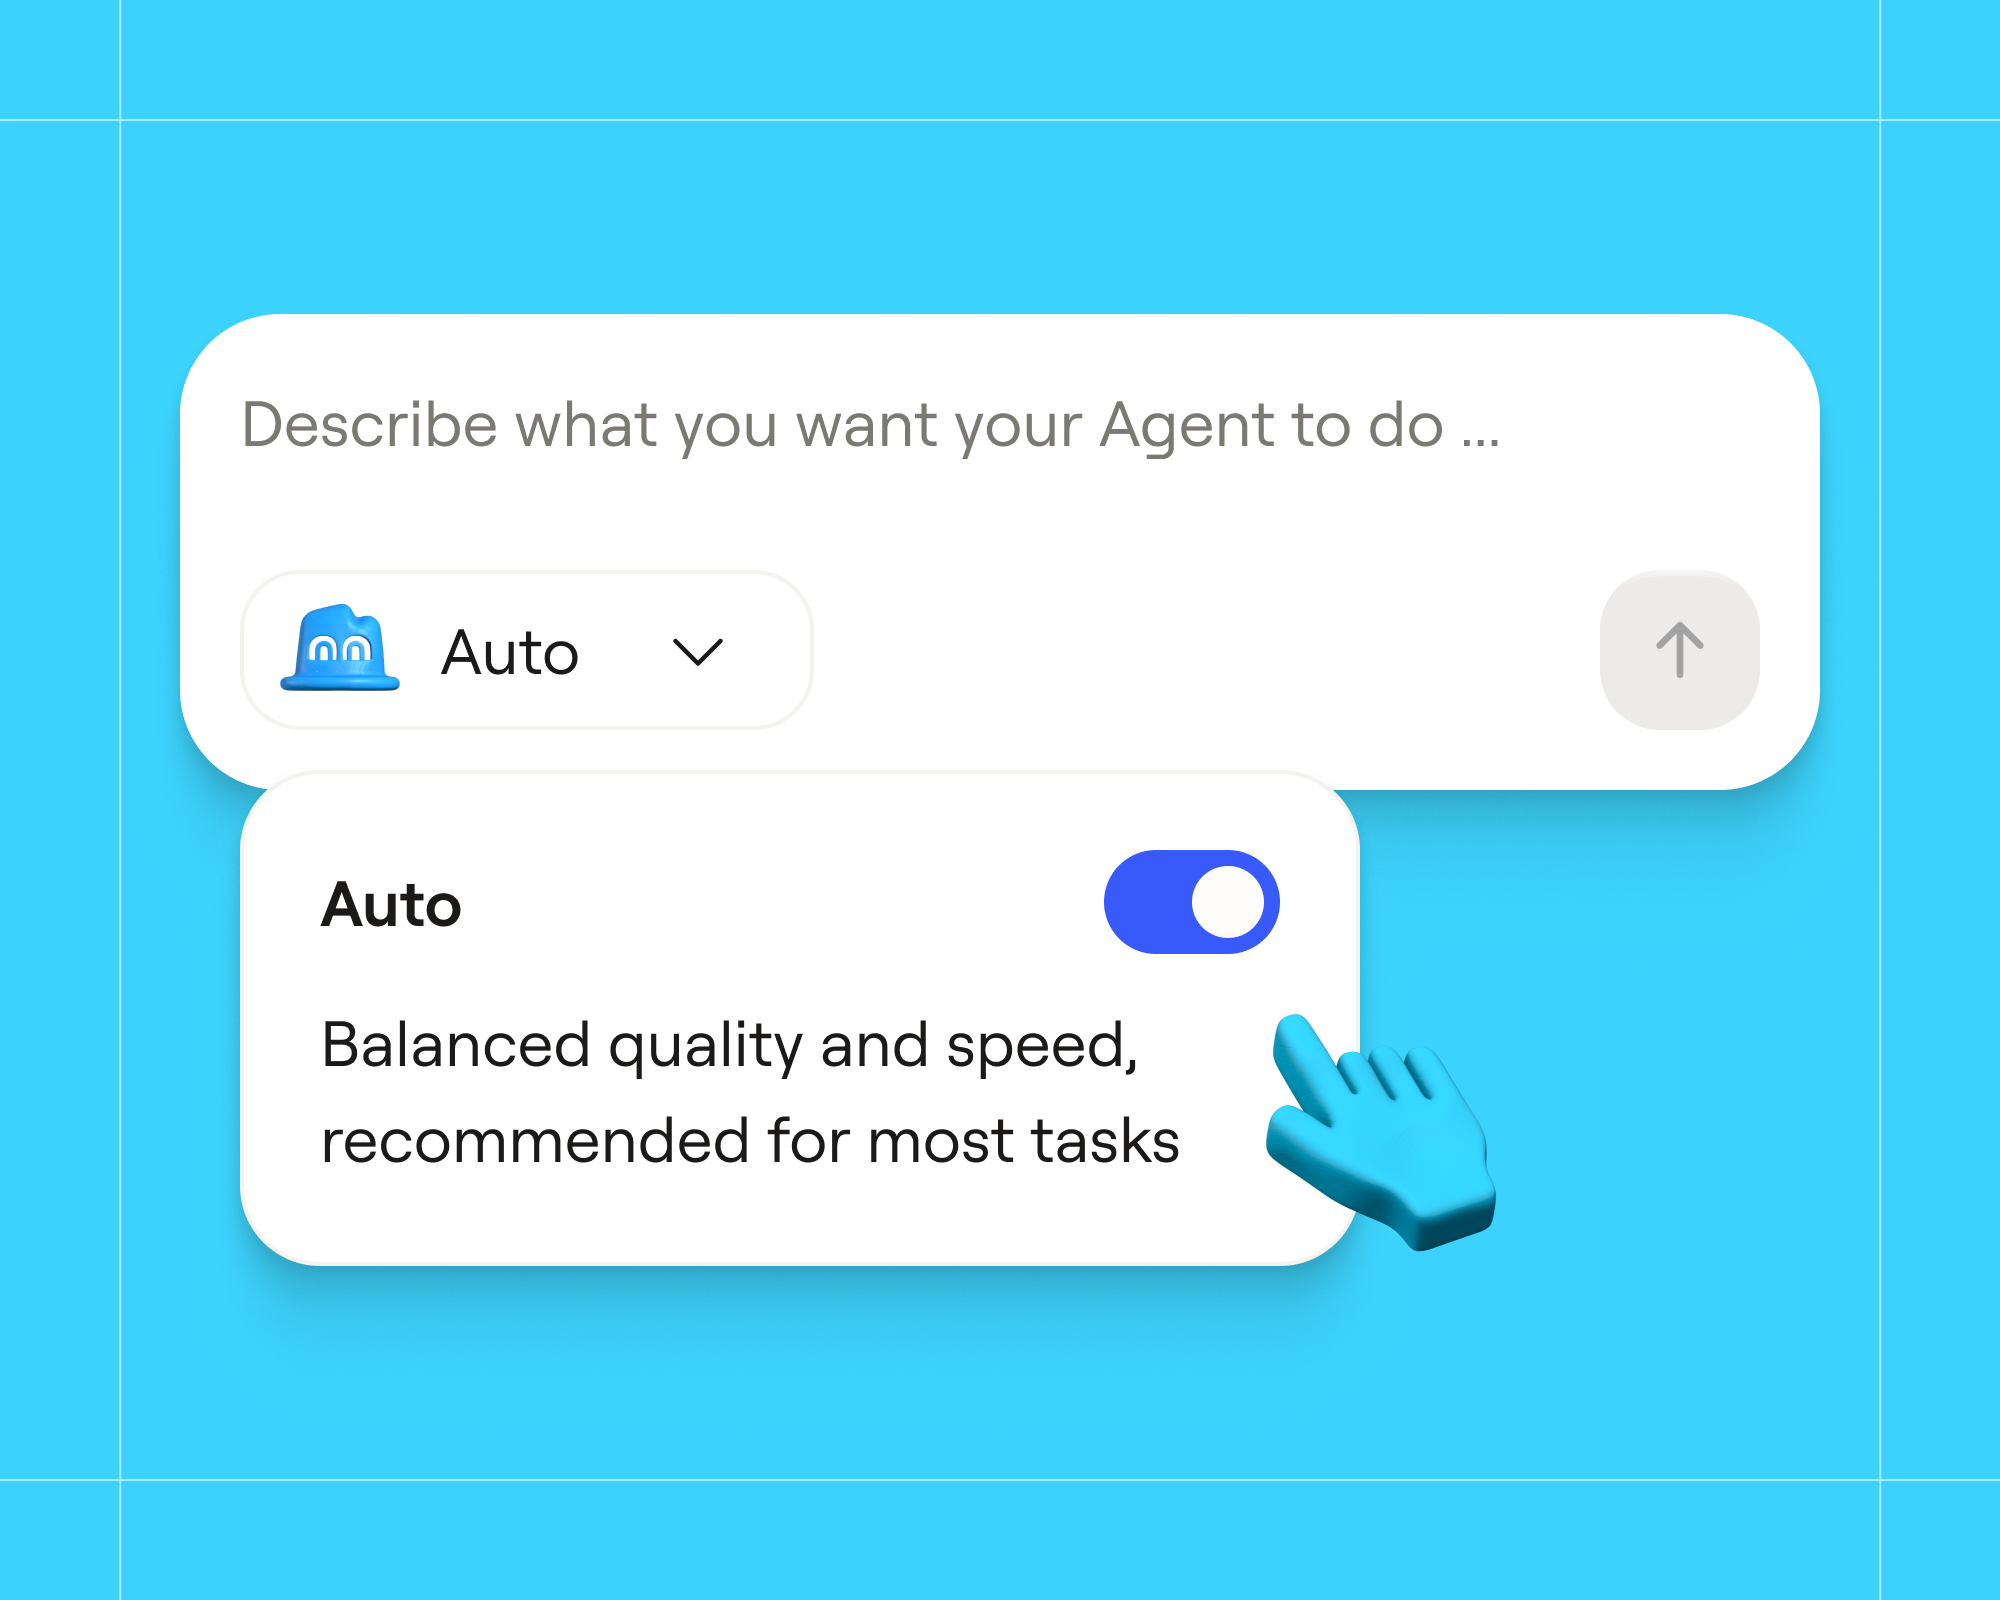
Clay's ML team recently launched Auto-mode in Claygent to help route each task to the right model. On production traffic, it costs 47% less than routing every task to the most capable model, while maintaining quality.
Claygents are Clay’s AI research agents and one of our most used tools, with over 5 billion runs to date. They handle go-to-market (GTM) tasks ranging from deep research to contact enrichment to outbound copywriting, running everywhere in Clay: workflows, tables, and Clay’s new global agent.
Users often run the same query over thousands of rows in their accounts table or records in their company audience, but the difficulty varies with both the task and the entity it targets. Finding the head of sales at a public company with a large web footprint might take a single lookup, while the same question about a ten-person startup can take several sources and some reconciliation. Sending every row to a frontier model overpays for the easy rows, while sending every row to a smaller model can fail on harder tasks.
The model frontier also changes daily, and most users don’t want to keep re-evaluating which model is best for each task. Auto-mode lets Clay do that work, routing each task to the model that best balances quality and cost.
What didn’t work
Before going straight to post-training a router, we tried some other approaches:
- A heuristic-based router that made decisions based on the task category, the popularity of the target entity (see our other blog post on CPJ metrics), the length of the request, and the complexity of the output.
- A decision model like Jev, with a prompt covering Clay’s GTM task types, common pitfalls for different request categories, and examples of easy versus hard requests.
Both performed poorly on our eval benchmarks (described below) compared with the final post-trained router. What made a query perform well on an easy model or fall short of a frontier model was too subtle and nebulous to write as rules or prompted business logic; it had to be learned.
How we trained the model router
The first step was getting a deep understanding of our Claygent data. We identified several common use cases, including company classification, deep web research, contact lookups, and personalized outbound message drafting.
Once we had our task categories, we worked with our partners at Applied Compute to generate thousands of synthetic tasks and their training labels, modeled on common GTM use cases.
Here are a few examples of synthetic Claygent queries and their task categories:
- Company classification: “Based on {company_domain}, is this a B2B company that sells products or services to other businesses? Answer only Yes or No.”
- Contact lookup: “Find a professional email address for {full_name} who works at {company_name}. Return only the email address.”
- Deep company research: “Analyze {domain} for AI adoption signals. Check job postings, blog, and press releases from the last 12 months. Return adoption level, confidence, and key excerpts.”
To label the data, each task was run through every candidate model that would be used in the router. An LLM judge graded each output against a correctness rubric to estimate each model’s performance. These scores were then used as training data for the router.
Applied Compute then post-trained a Qwen 3.6 35B model with a GRPO policy optimizing for category classification and score prediction accuracy. GRPO has the model generate several predictions for each query, scores each against the labels, and reinforces the ones that beat the group’s average.
How the router picks a model
At serving time, the router’s quality predictions are converted into a routing decision using a policy that minimizes cost and maximizes total utility. For a query q, the router outputs a predicted category ĉ(q) (ex: deep research) and a predicted quality score ŝ(q, m) for each candidate model m in the router. Since the actual cost of the task is unknown at routing time, we estimate it with C̄(ĉ(q), m), the selected model m’s average cost on reference queries in the predicted category. The router then selects the candidate that maximizes our utility function:
Essentially, utility = predicted score − scaling factor × expected cost.
In our utility function, λ sets the tradeoff between quality and cost. As λ increases, the router will pick smaller, cheaper models (as long as the quality drop is small).
The chart below shows the offline tradeoff between cost and quality at different λs, with quality scored by an LLM judge (described in the evaluation section).

Serving example
Here is an example routing query using a decision-maker lookup for a fictional company, ACME Corp.
After running Claygent searches for each of the candidate models, all of them found the right answer based on our rubric.
Every model gets this right, so routing to the cheapest model (5.4 Nano) is optimal. This was the router’s prediction of success for each model on this query:
Decision-maker / executive lookup uses a λ of 7.63. Multiplying it by each model’s average cost for this category gives the cost penalty in the utility function. At this λ, the cost penalty on Sol just exceeds its predicted quality gain, so Nano comes out slightly ahead.
In production, Auto-mode costs 47% less than sending every Claygent task to a frontier model, with comparable quality.
Evaluating the router
Before sending the router live traffic, we backtested it on a few weeks of sampled production requests. We re-ran each request through the Claygent harness once per candidate model, then scored each trace two ways.
Pairwise quality vs. Sol
A judge compared each candidate’s output to Sol’s output for the same request. It rated the candidate on a 5-point scale, from materially better to materially worse. Comparing against a reference gave us more consistent scores than grading each output on its own.
This approach measures whether a candidate can substitute for Sol, so it inherits Sol’s mistakes. If Sol gets a request wrong, a candidate that matches it still scores well.
Reference-free correctness
To measure correctness directly, we gave Claude Fable and GLM web research tools on a subset of requests. Each one verified a single model’s output at a time. This told us how often Sol, Mini, and Nano were actually wrong, and we used those results to calibrate the pairwise judge.
Checking the judge
LLM judges have known failure modes: position bias, bias toward their own model family, and nondeterministic scoring. We reran the pairwise judge several times on a sample of requests to test for each one. We swapped the order of the candidate’s output and Sol’s output, used different judge models, and compared scores across repeated runs.
Per-category lambdas
After evaluation, we decided to switch to per-category λs. Predicted scores and costs are distributed differently across query categories, so the same λ thresholds produced very different quality–cost tradeoffs from one category to the next.
To fit our λs, we ran a few thousand sampled production requests through the same backtest, giving us judged outcomes for every candidate, then ran the post-trained model over the same requests to get its predictions. For each category, we selected the λ with the lowest cost that still met our quality bar. We used repeated 3-fold cross-validation to check that the λs held up out of fold, then fit the final values on the whole sample.
Conclusion
We plan to keep iterating on the router with the Applied Compute team, improving performance across every GTM task so Claygents stay on the frontier. Auto-mode is just one example of what Clay’s MLE team is building toward: a product that gets smarter every time someone uses it. We’re also working on everything from semantic search, reranking models, knowledge graph and memory systems, and entity resolution. If that sounds like fun, we’re hiring.
Huge thanks to our partners at Applied Compute. Their blog post has more details on the training process.